The Industry's First
Network-Native
Inference Runtime.
Divide the payload. Aid the edge.
Not a cloud AI service. A distributed inference runtime. We shard open-weights SLMs across existing Cisco Catalyst 9300 Switches and CW917X Access Points via native Docker micro-containers. Leveraging asymmetric pipeline parallelism to run sovereign enterprise inference with zero dedicated GPUs.
Absolute Data Sovereignty.
Consider a financial institution processing highly sensitive PII. Employees using public, external AI tools create massive Shadow AI compliance breaches. Divaid keeps the prompt entirely localized, giving teams the AI they want while keeping the inference swarm physically sandboxed within the branch.
The 1,000-Node Compute Matrix.
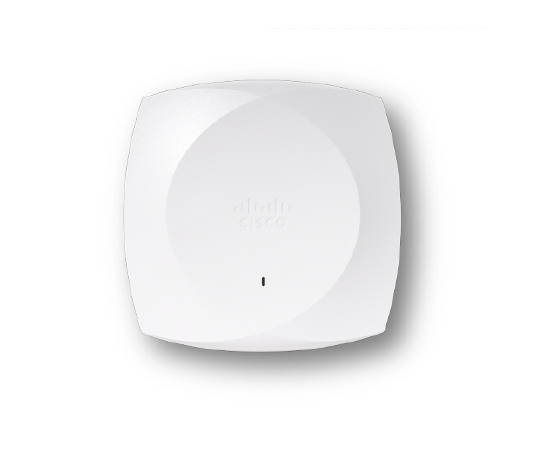
Deploying multi-million dollar GPU racks in every branch or campus is financially and energetically impossible. But scale changes everything. By harvesting dormant background cycles from the Catalyst Switches and Wi-Fi 7 Access Points already hanging from your ceilings, divaid.AI turns your existing network into an on-premise AI cluster with zero net-new power draw.
The Hidden Supercomputer: On-Premise vs. Cloud GPU
Aggregating just 100MB per AP yields over 100GB of working memory—surpassing the 80GB VRAM of a dedicated $15,000 NVIDIA A100 GPU.
Instead of renting expensive AWS instances, DDA awakens the massive, dormant multicore compute power already hanging from your ceilings.
APs run 24/7 via low-power PoE. We scavenge stranded background cycles, bypassing the massive multi-kilowatt (kW) footprint of cloud server racks.
Zero cloud API calls. By providing a secure, internal LLM, we effectively cure the enterprise Shadow AI problem while ensuring corporate IP never leaves the firewall.
AP-01 (CW917X Wi-Fi 7)
Real-World Flow: Asymmetric Pipeline Parallelism.
Processing a mission-critical 500-page Financial Audit or Live Network Triage without dedicated GPUs or cloud API egress. Rather than training a proprietary toy model, divaid.AI functions as an Asymmetric SLM Runtime & Partitioning Manager that shards standard open-weights models (Qwen-2.5, Llama-3.2, SmolLM2) across existing Cisco networking infrastructure:
1. Ingress Embedding (C9300)
Prompt tokenized in RAM; Ingress Embedding (W_embed) projects input tokens into initial activation vector x_0 (3.58 KB in FP16).
2. Sequential AP Pipeline Ring
Activation vector travels peer-to-peer across AP-01 → AP-02 → ... → AP-n over an isolated VLAN. Each AP executes 2 layers in 18 ms using bare-metal ARM NEON SIMD.
3. Zero-Disk-Write & Local KV-Cache
0 bytes written to flash (confined to volatile DRAM buffers). Localized KV-Cache reduces AP memory footprint to operate strictly within IOx cgroup boundaries.
4. LM-Head Projection & Sampling (C9300)
Final hidden state x_24 returns to C9300. High-speed AVX2/AVX-512 SIMD kernel projects d_model → V = 151,936 and samples the next token.
5. Multi-Swarm Task Recomposition
For massive audits (500 pages), multiple AP swarms (Vault, Teller, Risk) execute map-reduce chunks in parallel and merge into a sovereign report.
Cisco IOx & Native Docker Execution.
How does the fragmented workload execute inside individual nodes? Catalyst switches and modern edge APs possess robust ARM64 compute capacity. Cisco IOx allows native Docker containers to run directly on the hardware under strict cgroups. Here is how our three-phase pipeline makes it possible:
GGUF Encoding
We subject state-of-the-art dense transformer models to aggressive INT4 quantization. By dropping precision on the weight matrices, the payload is algorithmically compressed, fitting inside the Docker image without perplexity degradation.
The DivGraph™ Algorithm Patent Pending
Our proprietary DivGraph Distribution Architecture coordinates decentralized edge inference directly inside the local network. When an enterprise task arrives, DivGraph partitions model execution across the AP swarm, while keeping vocabulary matrices pinned to the switch orchestrator. Parameter weights remain completely local, with zero cloud egress.
C9300 Merge
Once the AP nodes complete their fraction of the calculation, the tensors return to the C9300. The Orchestrator acts as the ultimate verifier, recombining the mini-tasks, decoding the hidden states, and returning the definitive final AI output with mathematical certainty.
Hardware-Level Isolation.
How do we run Generative AI across the network without impacting mission-critical connectivity? By leveraging Cisco IOx to enforce an airtight, hardware-level sandbox with absolute priority for line-rate traffic.
90% Dedicated to Wi-Fi 7
The vast majority of the AP's CPU, RAM, and NPU are completely untouched. Core network services have absolute priority at the hypervisor level.
10% divaid.AI Sandbox
We deploy the DDA Worker node via Docker cgroups. It is mathematically bounded to never exceed 100MB of RAM or interrupt network thread execution.
Micro-Orchestration on Catalyst.
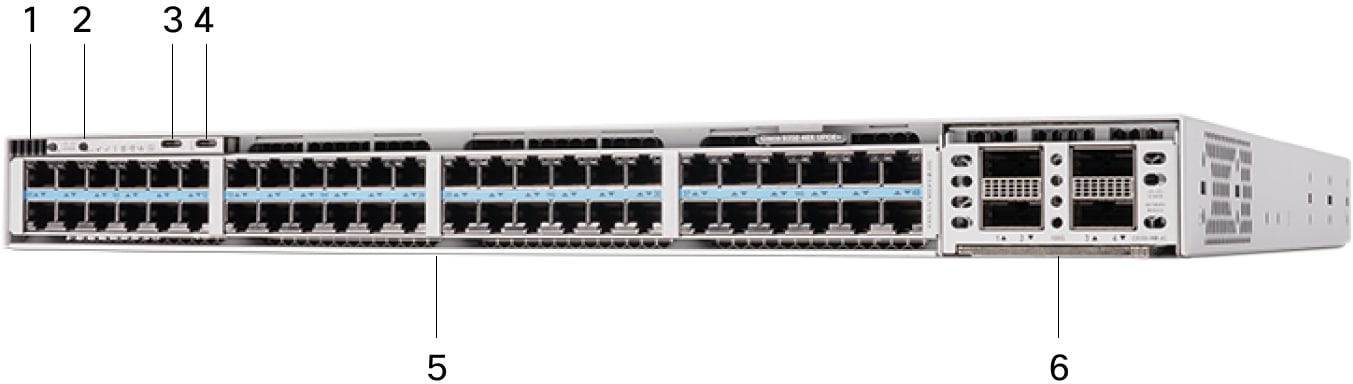
The Catalyst 9300 Series switches act as the central brain. Instead of routing standard packets, our lightweight IOx app routes tensor states.
Untouched ASIC Performance
The UADP ASIC continues to switch enterprise traffic at line rate. divaid.AI does not interact with or degrade the data plane hardware switching.
Lightweight Master Node
A tiny fraction of the switch's application hosting CPU handles the DDA algorithm, keeping track of which AP is processing which neural layer.
Target Sectors for Sovereign AI.
Public cloud LLMs are commercially unviable for highly regulated industries due to data privacy laws. divaid.AI provides a secure, fully-managed alternative to unsanctioned public tools, eradicating the Shadow AI problem for sectors where data can never leave the building.
Food Retail & Supermarkets
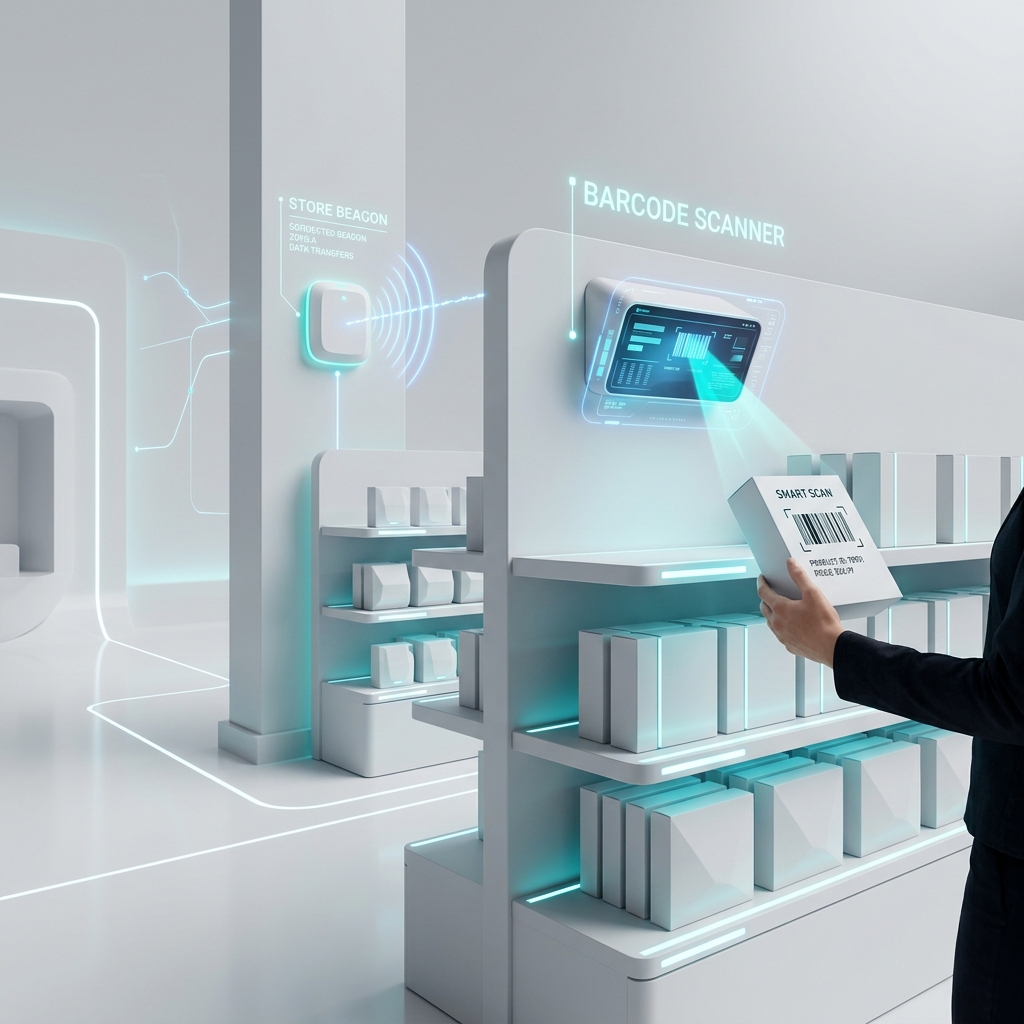
Multimodal Edge AI across hundreds of grocery stores without per-store GPU servers: real-time shelf stock-out detection, fresh produce shrinkage (merma) control, OCR price-tag vs. POS auditing, and EAN-13 dock verification directly on store Wi-Fi 7 APs.
Healthcare & Hospitals
Real-time processing of patient telemetry, automated clinical transcription, and diagnostic RAG systems running locally on the hospital's Catalyst-backed VLAN. 100% HIPAA compliant.
Banking & Branches
Processing highly sensitive Personally Identifiable Information (PII) and internal audits. The branch network infrastructure executes the Generative AI tasks without relying on external corporate APIs.
Government & Defense
Execution of intelligence models on classified data. The network itself becomes an air-gapped supercomputer, ensuring National Security compliance (ENS/FedRAMP) by default.
Smart Manufacturing
Ultra-low latency decision making for industrial automation. By moving inference directly to the physical APs covering factory floors and logistics hubs, round-trip cloud latency is eliminated entirely.
Energy & Utilities
Sovereign AI for power substations, water treatment facilities, and smart utility grids. Ensures strict operational continuity and anomaly detection in mission-critical environments disconnected from the public internet.
Supermarket & Food Retail Chains: In-Store Camera Vision Processed Directly by the Store Network.
Grocery chains operate on tight 1.5%–3% margins across hundreds of stores. Streaming 30–50 aisle cameras per store to the cloud saturates store WAN links, inflates cloud bills, and creates severe GDPR risks by filming shoppers. Installing dedicated GPU servers in every store is CapEx-prohibitive. DIVAID™ turns the store's existing PoE cameras, Catalyst switch orchestrator, and ceiling Wi-Fi 7 APs into an autonomous visual intelligence cluster:
1. Store Cameras & Scales
Aisle IP PoE cameras, fresh-produce scales, dock scanners, and staff PDAs capture shelf, label, and queue snapshots over the local VLAN.
2. Catalyst Orchestrator
Extracts 64 visual tokens (3×3 shelf-gap grid, OCR prices/dates, EAN-13 barcodes, anonymous density) and discards the raw photo in RAM (GDPR).
3. Wi-Fi 7 AP Swarm
Ceiling CW917X APs execute the sharded INT4 SLM (<96 MB DRAM/AP, 0B Flash writes, Scavenger QoS CS1) to evaluate store rules.
4. Real-Time Store Action
Sends instant restock orders to clerk PDAs, dynamic -30% markdown stickers, POS price mismatch alerts, and checkout opening triggers.
1. Shelf State & Stock Replenishment
Detects dark shelf gaps (Out-of-Shelf) via 3×3 spatial analysis, reads the empty slot's SKU via OCR, checks backroom stock, and dispatches restock orders to staff PDAs—recovering 3–5% of lost sales.
2. Inventory & Dock EAN-13 Reception
Decodes EAN-13 / GS1-128 barcodes and supplier delivery notes via OCR at unloading docks, enforcing minimum remaining shelf-life rules (>75% before expiry) and reconciling ERP stock.
3. Fresh Produce Shrinkage (Merma)
Evaluates color oxidation on fruit, bakery, and meat trays alongside OCR lot dates—recommending dynamic -30% yellow markdown stickers before closing to cut fresh waste by 15–25%.
4. Price-Tag & Promo OCR vs. POS
Audits printed shelf price tags and 3x2 promo signage via OCR against the store POS database, eliminating checkout price disputes and expired promotional banners.
5. Shopper Behavior & Queue Analytics
Computes anonymous aisle heatmaps, promo end-cap conversion, and checkout queue wait times in volatile RAM to open new cashiers dynamically—100% GDPR compliant with zero stored faces.
6. Cold-Chain HACCP & Self-Checkout
Reads digital thermometer displays on chillers/freezers via OCR (>5 °C alert) to prevent spoilage, and verifies produce items at self-checkout scales to reduce unknown shrinkage.
The Live Lab at Cisco Innovation Center BCN.
A turnkey, physical proof-of-concept environment deployed inside Cisco's flagship Innovation Center in Barcelona. Demonstrating live, air-gapped sovereign LLM inference distributed across enterprise switching and Wi-Fi 7 access points with zero cloud egress.

IOx Master SSD-240G. Tensor sharding.
INT4 inference mesh (<84MB/AP).
Shelf Stock-Out, Shrinkage & OCR/EAN-13 Auditing
Use Case: Supermarket chains lose 3–5% of sales to shelf stock-outs and 15–25% of fresh margins to produce shrinkage (merma), while cloud video backhaul across 500+ stores is cost-prohibitive and GDPR-sensitive.
How We Prove It: Vision Encoder + OCR + EAN-13 barcode scanner feeding a sharded SLM across store Wi-Fi 7 APs (<96 MB RAM/AP, 0B Flash writes) to trigger real-time restock, markdown, and POS price-mismatch alerts locally.
On-Premises Branch AML SWIFT Scoring
Use Case: 50,000 real-time audited SWIFT transactions. Eliminates banking Shadow AI vulnerabilities by processing financial records and PII strictly inside the branch perimeter.
How We Prove It: Centralized orchestration on the Catalyst 9300. Llama-3.1 8B runs sandboxed in IOx micro-containers over the branch VLAN without external GPUs or cloud dependencies.
Absolute Wi-Fi 7 QoS & Traffic Priority
Use Case: The non-negotiable requirement of any CTO or network architect: guarantee that enterprise mission-critical traffic, voice, and 4K video suffer zero degradation.
How We Prove It: Live synthetic traffic spike saturating AP-04. The Scavenger scheduler throttles AI inference to 0% CPU in 3.8 ms, migrating tensors with 0.0% packet drop.
Accelerating Cisco's 'Network for AI' Vision.
divaid.AI transforms the network from a mere transport layer into a distributed Secure AI Factory. By pioneering the Cisco Unified Edge for GenAI inference, we execute directly on Cisco's "AI-Ready Infrastructure" mandate, aligning perfectly with the core objectives of the Country Digitalization Acceleration (CDA) program.
Ideal for accelerating hardware refreshes in clients with obsolete infrastructure, pushing them toward Catalyst 9300 switches and CW917X APs. For clients who already own supported hardware, it provides a massive, immediate value-add.
Positions Cisco and its Partners as undisputed pioneers in a new category: Local AI Processing on Network Infrastructure. Currently, no other global vendor offers the capability to execute GenAI workloads natively across their switching and wireless fabric.
Provides a natural evolutionary path. As the client's GenAI demands grow, divaid.AI paves the way for future deployments of dedicated Cisco AI Pods, reinforcing their long-term strategy for secure, sovereign local AI.
Creates lucrative opportunities for the Cisco Partner Ecosystem. Drives profitable Professional Services (AI readiness audits, mesh deployments) and guarantees sticky, long-term Managed Service Provider (MSP) revenues.
